The rapid integration of Large Language Models (LLMs) into enterprise workflows has created a significant divide between casual users and technical practitioners. As businesses move from experimental chatbots to production-grade automation, the industry has seen a rise in "prompt engineering" as a discipline. However, a critical distinction is emerging: the difference between designing a prompt from scratch and the rigorous process of prompt optimization. While engineering focuses on initial architecture, optimization is the iterative, evidence-based process of refining existing prompts to handle edge cases, maintain reliability, and ensure output consistency without modifying the underlying model weights.
The Problem with Intuitive Prompting
For most developers, the initial interaction with an LLM begins with a natural language query. While this often yields coherent prose, it frequently fails in professional environments where output must be parsed by downstream software. When an LLM generates a conversational list of action items from a meeting transcript, it may appear accurate to a human reader, but it often lacks the structural integrity required for integration into project management tools like Jira, Trello, or custom internal databases.
The gap between "plausible" output and "functional" output is where most AI projects stall. A model that misses a reassignment of tasks or invents a deadline is not merely inconvenient; it represents a failure of reliability. To bridge this, engineers are increasingly moving away from "prompt hacking"—guessing at which adjectives might improve performance—toward a structured, empirical methodology.
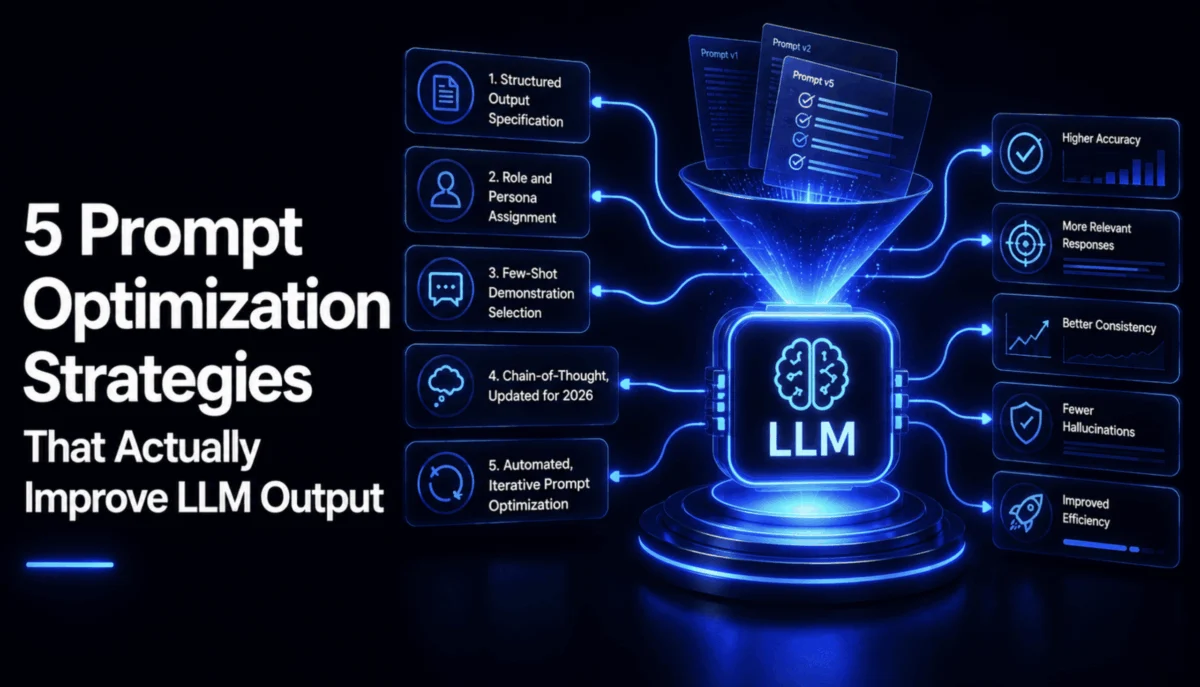
Strategy 1: The Mandate for Structured Output
The most immediate hurdle in production environments is the lack of machine-readable data. Relying on an LLM to generate plain text is the primary cause of integration failure. By implementing strict schema enforcement, such as those provided by the Pydantic library in Python, developers can move from probabilistic text generation to deterministic data handling.
In a controlled test of meeting transcript parsing, a prompt requesting a "list of action items" failed entirely to produce valid JSON, resulting in a parsing error. Conversely, by providing the model with a predefined Pydantic schema—specifically defining fields for owner, task, and due_date—the output transitioned from unstructured prose to a validated object. This transformation is essential; in an enterprise setting, an unparseable response is a hard failure that requires immediate automated handling, rather than a "softer" error that a human must manually correct.
Strategy 2: Contextual Role-Play and Persona Adoption
While often dismissed as a gimmick, assigning a persona is a mathematically verifiable way to steer a model’s latent space. When a model is instructed to act as a "meticulous executive assistant," it accesses training data associated with precision, administrative oversight, and conflict resolution.
For complex transcripts—such as those involving mid-meeting task reassignments—a generic instruction often fails to capture the final intent. By contrast, a persona-driven prompt primes the model to expect ambiguity. In the case of a transcript where Priya initially offers to review a layout but later delegates it to Jake, the "executive assistant" persona is significantly more likely to prioritize the final, confirmed assignment over the initial utterance. This is not about politeness; it is about activating the specific clusters of reasoning that a professional assistant would employ to avoid errors.
Strategy 3: The Science of Few-Shot Selection
The "few-shot" method, which provides the model with examples of desired input-output pairs, is a cornerstone of prompt optimization. However, research suggests that the quality of these examples is secondary to their diversity. A common error is providing three examples that are essentially minor variations of the same scenario. This leads to model overfitting, where the AI fails to generalize to novel edge cases.
Using a Tfidf (Term Frequency-Inverse Document Frequency) vectorizer combined with cosine similarity analysis, developers can programmatically ensure that few-shot examples cover distinct logical patterns. For instance, a robust set of examples would include:
- An item with a confirmed owner and deadline.
- An item where ownership is left unresolved.
- An item that is merged into a previous action rather than listed separately.
By selecting examples that are mathematically dissimilar, the developer ensures the model learns the logic of the task rather than just mimicking the format of the examples.
Strategy 4: Chain-of-Thought and Reasoning Optimization
The "Chain-of-Thought" (CoT) technique—instructing the model to "think step-by-step"—has evolved alongside the architecture of frontier models like GPT-4 and Claude 3.5. While modern models exhibit some native reasoning capabilities, explicit CoT instructions remain vital for complex, ambiguous tasks.
The utility of CoT is most apparent in scenarios involving temporal logic. In a meeting transcript, if a task is mentioned, reassigned, and then modified by a secondary constraint, a standard model may default to the first mention. By forcing a "reasoning draft" before the final output, the developer creates an audit trail for the model. For cost-sensitive operations, the "Chain of Draft" method—which limits reasoning steps to brief phrases—has been shown to maintain accuracy while reducing token consumption by over 90%, providing a pathway to high performance without ballooning operational costs.
Strategy 5: Automated Iterative Optimization
The final, most sophisticated step is the transition from manual tuning to automated search. By treating a prompt as a collection of modular fragments, developers can run a hill-climbing algorithm to identify the most effective combination of instructions.
In a recent simulation, a baseline prompt for parsing meeting transcripts achieved a 51.6% accuracy score. By systematically adding and testing specific fragments—such as "use the final owner, not the first" or "merge duplicate items"—the system reached a 100% accuracy rate within three iterations. This approach removes the subjective bias of the engineer, ensuring that only the instructions that demonstrably move the needle are retained.
Broader Implications for Enterprise AI
The shift toward evidence-based prompt optimization has significant implications for how companies deploy AI. As AI becomes a foundational layer of the software stack, the reliability of these systems becomes a matter of fiscal and operational integrity.
According to industry analysts, the "black box" nature of early LLM interactions is being replaced by systematic testing frameworks. This evolution suggests that the future of prompt engineering will look less like creative writing and more like quality assurance testing. As these methodologies standardize, the barrier to entry for building high-reliability AI agents will lower, while the competitive advantage for firms that adopt these optimization protocols will widen.
Conclusion
Prompt optimization is the bridge between the potential of generative AI and the requirements of production-grade software. By moving away from anecdotal changes—such as tweaking the wording of an instruction—and toward a model of rigorous, data-driven refinement, developers can eliminate the subtle, persistent errors that plague early-stage AI implementations. Whether through structured output schemas, diverse few-shot examples, or automated hill-climbing searches, the goal remains the same: transforming an unpredictable probabilistic engine into a reliable, deterministic tool for business intelligence.