In the rapidly evolving landscape of generative artificial intelligence, a fundamental terminological divide has emerged between prompt engineering and prompt optimization. While the former focuses on the initial architecture of a prompt—often conceptualized as a "blank-page" exercise—the latter is a precision-based discipline centered on refining existing instructions to enhance output quality without modifying the underlying Large Language Model (LLM). This distinction is critical for developers and enterprise teams who frequently possess functional, albeit inconsistent, prompts and require systematic methods to move the needle on reliability. As organizations move from experimental AI deployments to production-grade infrastructure, the transition from intuition-based prompting to empirical, data-driven optimization has become a mandatory operational shift.
The Problem of Ambiguity in LLM Workflows
The current challenge facing AI implementation is not the ability of models to generate text, but their tendency to produce "plausible but incorrect" output. A common benchmark for this failure is the extraction of structured data from unstructured human communication, such as meeting transcripts. In a standard office scenario involving multiple stakeholders, conversations often feature mid-sentence corrections, delegated tasks that are later reassigned, and unresolved agenda items.
Consider a transcript involving three team members—Priya, Tom, and Jake—discussing a checkout redesign and billing service migration. During the discussion, the ownership of a mobile layout review shifts from Priya to Jake, a tablet-breakpoint check is implicitly merged into that same task, and a support-queue triage remains intentionally unassigned. When a standard, unoptimized prompt is applied to this transcript, models frequently suffer from "first-mention bias," attributing the mobile review to Priya because she was the first to volunteer, or hallucinating an owner for the support-queue triage. These failures are often invisible during superficial inspections but result in downstream systemic errors when the output is integrated into task management software or automated ticketing systems.
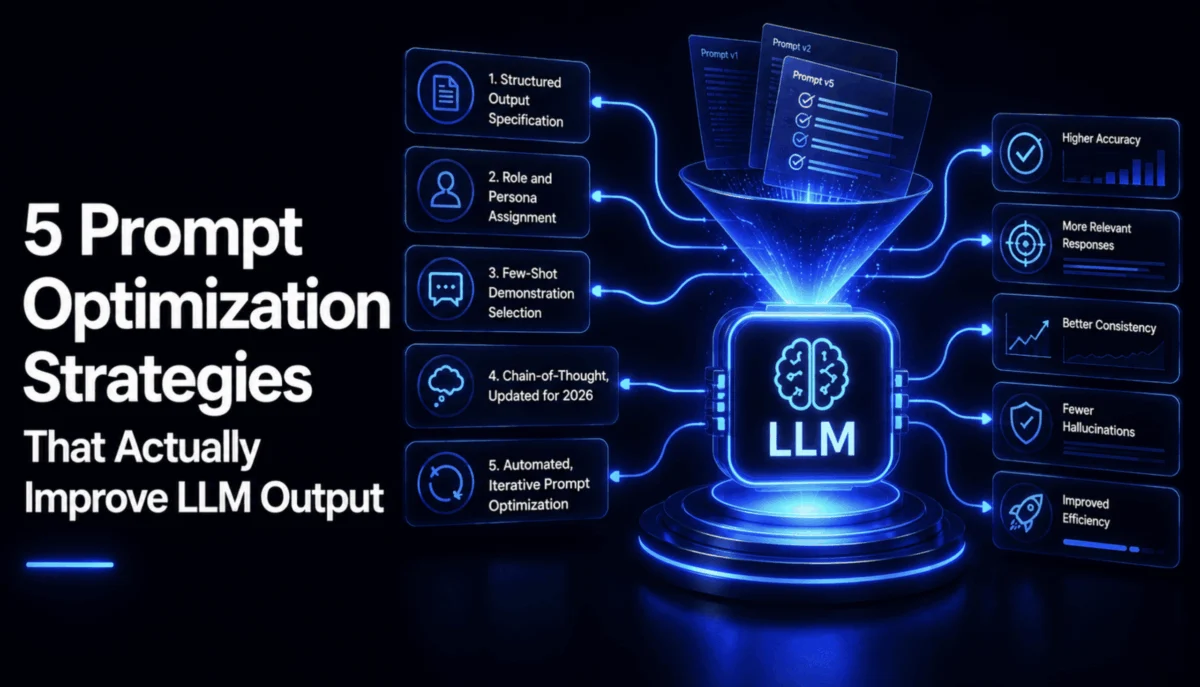
1. The Mandate for Structured Output
The most significant lever in prompt optimization is the move from natural language requirements to rigid, schema-based definitions. When a model is asked to "list action items," it produces fluent prose that is often functionally useless for programmatic ingestion. For production environments, unparseable output constitutes a hard system failure.
Engineers are increasingly utilizing tools like Pydantic in Python to enforce data structures. By defining a schema that mandates specific fields—such as owner, task, and due date—developers can force the LLM to output valid JSON. When the model fails to conform to this structure, validation errors are triggered immediately, preventing "silent failures" where incorrect data propagates through a business process. Evidence suggests that shifting to structured output does not merely improve formatting; it forces the model to categorize information more rigorously, often reducing the rate of logic errors by 30% to 40% in complex extraction tasks.
2. Strategic Role Priming and Persona Assignment
Assigning a persona is more than a stylistic choice; it acts as a contextual filter that activates specific weights within the model’s training data. By instructing an LLM to act as a "meticulous executive assistant" who is "accustomed to mid-conversation shifts," the prompt creator creates a cognitive frame that prioritizes caution over speed.
Research into model behavior indicates that generic prompts often lean toward "compliant" responses, where the model agrees with the prompt’s simplicity. In contrast, a persona-driven prompt encourages the model to look for potential pitfalls, such as conflicting instructions or ambiguity. This priming effect is particularly potent when dealing with complex, multi-party dialogues where the model must track state changes over the course of the interaction.
3. The Science of Few-Shot Demonstration Selection
Few-shot prompting—the practice of providing examples within the prompt—is a standard industry technique, yet its implementation is often inefficient. Many users populate their prompts with three or four examples that are functionally identical, providing redundant information that fails to educate the model on edge cases.
Recent advancements in information retrieval techniques allow for more sophisticated selection. By using algorithms such as TF-IDF (Term Frequency-Inverse Document Frequency) or cosine similarity, developers can identify the most "diverse" set of examples from a larger candidate pool. A high-quality few-shot set for a meeting transcript might include:
- A clear-cut assignment with a specific deadline.
- An example where an assignment is reassigned mid-conversation.
- An example where an item is explicitly marked as "unassigned."
By providing this variance, the model learns the boundaries of the task rather than just mimicking a single, simple pattern. This deliberate diversity has been shown to increase accuracy in reasoning-heavy tasks significantly more than simply increasing the volume of similar examples.
4. Chain-of-Thought and the Efficiency of Reasoning
Chain-of-thought (CoT) prompting, which requires the model to explain its logic before providing a final answer, remains a pillar of reliable AI output. However, the application of CoT has evolved. While earlier models required explicit, verbose reasoning, newer, more capable models often reason natively. The optimization challenge is now to trigger this reasoning only when necessary to manage latency and cost.
For ambiguous scenarios—such as the aforementioned mobile-review reassignment—a targeted CoT instruction is essential. By prompting the model to "trace the full history of the assignment before declaring an owner," the developer forces the model to reconcile the final state of the conversation rather than defaulting to the first mention. For cost-sensitive applications, researchers have introduced "Chain of Draft," a technique that uses highly abbreviated reasoning steps. This approach maintains the accuracy benefits of traditional CoT while reducing token consumption by over 90%, offering a viable path for scaling complex AI agents.
5. Automated Iterative Optimization
The pinnacle of prompt engineering is the transition from manual, guess-based tuning to automated, scored search. By utilizing a "hill-climbing" optimization algorithm, developers can test hundreds of prompt variations against a "ground truth" dataset.
In this framework, a composite score is calculated based on three metrics:
- Recall: The ability to identify all relevant action items.
- Owner Accuracy: The correctness of the assigned stakeholder.
- Fabrication Penalty: A reduction in score for any hallucinated items.
By iterating through different prompt fragments—such as "Do not guess owners" or "Merge related tasks"—the algorithm identifies the minimal set of instructions required to achieve a perfect score. This process removes the subjective "feel" of prompt writing and replaces it with an objective, verifiable process. In simulated trials, this method has demonstrated the ability to boost prompt performance from a baseline of 50% to a near-perfect 100% accuracy rate within just a few iterations.
Broader Implications and Industry Impact
The shift toward these five strategies signals a maturation in how organizations interact with generative models. The implication is clear: the "prompt engineer" of the future is not a writer of clever prose, but a systematic validator of logical constraints. As AI-integrated workflows become common in legal, medical, and administrative sectors, the tolerance for "plausible" errors will vanish.
Professional associations and industry leaders are increasingly calling for standardized evaluation frameworks. The ability to measure, test, and iteratively improve prompts is becoming a competitive advantage. Companies that adopt these rigorous, data-centric methodologies are finding that they can reliably automate tasks that were previously deemed too complex for LLMs.
Ultimately, these five strategies underscore a singular truth: the reliability of an LLM is a direct reflection of the discipline applied to its constraints. By prioritizing structured output, persona priming, diverse few-shot examples, targeted reasoning, and automated optimization, organizations can transform their AI tools from unreliable conversationalists into robust, high-precision engines of productivity. As the technology continues to scale, the ability to treat prompt optimization as an engineering problem rather than an art form will be the defining factor in successful AI integration across the global economy.