In the evolving landscape of artificial intelligence, Small Language Models (SLMs) are increasingly recognized as the backbone of efficient, cost-effective automation. While massive Large Language Models (LLMs) often dominate the headlines, businesses seeking to implement narrow automation—such as classification, sentiment analysis, or structured data extraction—are finding that models in the 0.5B to 3B parameter range offer superior latency and operational costs. Building on previous research regarding output space constraints, this report examines a second critical strategy for SLM optimization: the strategic reuse of prompt prefixes via Key-Value (KV) caching.
The Problem of Redundant Computation in Automated Workflows
Narrow automation tasks, such as classifying customer support tickets or parsing incoming web leads, rely on static "system prompts." These instructions typically include complex taxonomy definitions, few-shot examples, and strict formatting requirements that remain consistent across thousands of individual requests. In a naive implementation, an inference engine processes the entire block of static text—often hundreds of tokens—every time a new input is provided.
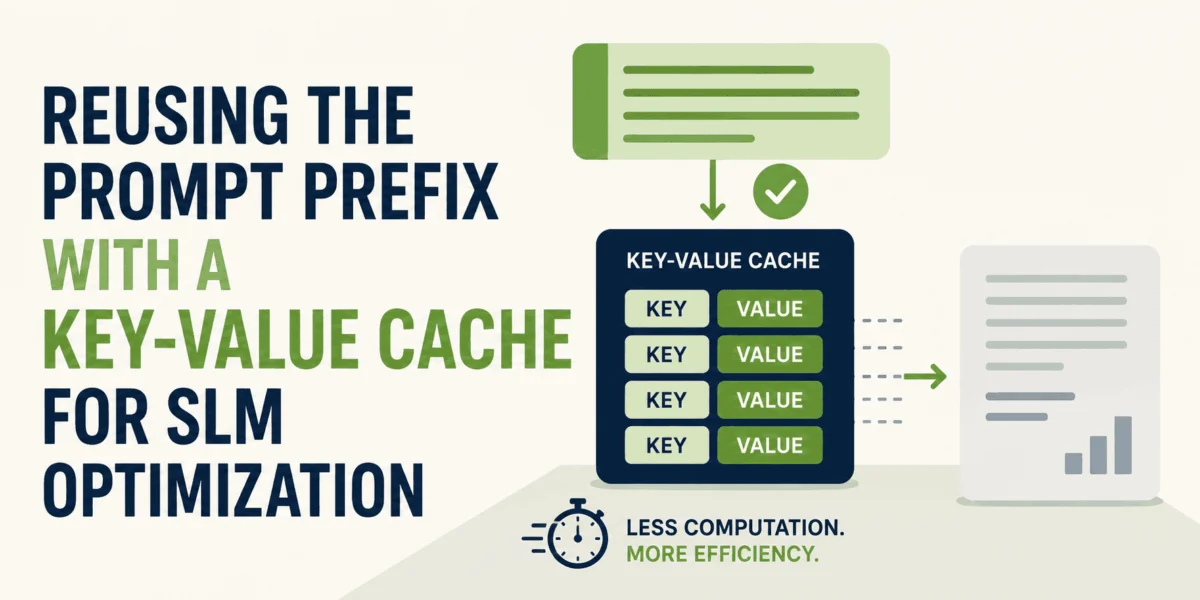
This approach is computationally expensive. When a model re-encodes the entire instruction set for every ticket, the vast majority of the "pre-fill" phase involves calculating vectors that have already been generated in the previous request. Transformers compute key and value vectors for each token at each layer based on preceding tokens. If the preceding tokens (the system prompt) are identical, the resulting key-value pairs are mathematically redundant. By computing these once and storing them in memory, developers can reduce the per-item workload to only the novel tokens that differ between instances, such as the unique content of a specific support ticket.
Chronology of Optimization Strategies
The shift toward optimizing SLMs has accelerated as organizations move from research environments to production-grade deployments. The timeline of this optimization evolution generally follows three phases:
- The Naive Integration Phase: Early deployments treated language models as black-box APIs, sending the full prompt context with every request. This led to high latency and unnecessary CPU/GPU utilization.
- Output Constraining: As demonstrated in preceding industry benchmarks, limiting the output space—forcing the model to choose only from predefined logits—reduced the need for extensive token generation. This allowed for single-forward-pass classification, effectively turning a generative model into a high-speed classifier.
- Context Reuse (KV Caching): The current phase focuses on minimizing the "time to first token" by caching the static prefix. This technique, while well-known in high-performance inference servers, is now being successfully applied to local, lightweight SLM implementations, such as those running on consumer hardware like the Apple M2 series.
Technical Performance Analysis: Baseline vs. Cached Implementation
To quantify the efficiency gains of prefix caching, industry benchmarks using the Qwen2.5-0.5B-Instruct model provide a clear empirical picture. When processing a batch of 600 customer support tickets, the baseline method—re-encoding the full prompt for every entry—required 184.85 seconds to complete. The prompt consisted of a 145-token static instruction block and a variable user input, resulting in an average processing time of 308.1 milliseconds per ticket.
By implementing a DynamicCache mechanism, the static instruction block was encoded exactly once. For subsequent tickets, the inference engine injected only the unique ticket data, referencing the pre-computed key-value pairs stored in the cache. The performance results were significant:
- Baseline Runtime: 184.85 seconds (308.1ms per ticket)
- Cached Runtime: 80.07 seconds (133.5ms per ticket)
- Efficiency Gain: ~57% reduction in total compute time
These findings suggest that for applications where instructions are long and input data is short, the performance benefits of KV caching grow exponentially. The more complex the system prompt, the greater the efficiency advantage, as the model avoids re-parsing the core logic of the task.
Theoretical Implications for Production Environments
The ability to maintain high-performance, consistent model behavior on modest hardware has profound implications for enterprise AI. For organizations concerned about data privacy and latency, the transition from cloud-dependent LLMs to local SLMs is now a viable architectural path.
By "warming" the model with a static prefix, developers can effectively create a specialized agent that remains ready to classify or process incoming data with minimal overhead. This technique does not alter the model’s weights or its decision-making logic; it is a pure computational optimization. Consequently, the accuracy of the model remains identical to the naive approach, while the cost of infrastructure—measured in electricity, compute time, and server occupancy—is more than halved.
Scalability and Future-Proofing Narrow Automation
As the industry matures, the focus on "narrow automation" highlights a shift in sentiment. Rather than attempting to solve every problem with a singular, massive model, the industry is trending toward a "symphony of specialists." In this architecture, small, optimized models are assigned specific, repetitive tasks.
The technical implementation of prefix caching requires careful attention to "token-clean" splits. As the documentation for various tokenizer libraries indicates, if the concatenation of a prefix and a suffix does not yield the exact same token IDs as encoding the entire string simultaneously, the KV cache will become misaligned. This necessitates rigorous validation during the development cycle, ensuring that the static prefix boundary matches the tokenizer’s expectations perfectly.
Expert Perspectives on Lightweight AI
Industry researchers note that the democratization of high-quality, small-scale models has changed the economics of software development. Previously, the cost of running a model for thousands of classifications was prohibitive. With optimization techniques like KV caching, the cost-per-inference drops to levels that compete with traditional rule-based programming.
"Small language models are no longer a compromise," says one researcher familiar with current optimization benchmarks. "When you wrap an SLM in a well-architected pipeline that includes output space constraints and intelligent caching, it becomes the most logical solution for structured, high-volume tasks. It is robust, predictable, and remarkably fast."
Broader Impact on the Data Science Community
The move toward these optimization techniques represents a broader goal: making AI accessible. By providing clear frameworks for reducing the compute burden, the community is moving away from a "more compute is better" mentality. Instead, efficiency is becoming a core metric of model quality.
Furthermore, the environmental impact of these optimizations should not be overlooked. With thousands of companies integrating AI into their daily workflows, a 57% reduction in compute time for a single routine task represents a massive cumulative saving in power consumption across the global data center infrastructure.
Conclusion
The evolution of SLM optimization is currently defined by the transition from generic prompting to highly structured, cached, and constrained execution. As developers continue to refine these workflows, the integration of AI into backend systems will become increasingly seamless. By treating the prompt prefix as a static, reusable resource rather than dynamic data, organizations can unlock a new level of performance, turning Small Language Models into a cornerstone of the modern automated enterprise. The technical barriers to entry are lowering, and the path to production-ready, local-first AI is clearer than ever before.