The deployment of Small Language Models (SLMs) in production environments has transitioned from an experimental curiosity to a cornerstone of enterprise efficiency. As organizations seek to automate narrow, repetitive tasks—such as classifying customer support tickets or parsing structured data—the computational overhead associated with full-model inference has become a critical bottleneck. In a series of technical examinations regarding SLM optimization, the focus has shifted toward minimizing redundant compute cycles. Following a previous analysis on constraining output spaces, this report details the implementation of prompt prefix caching, a technique that allows developers to achieve significant latency reductions by leveraging the static nature of system instructions.
The Architecture of Redundancy
In standard transformer-based architectures, every inference request triggers a complete re-encoding of the input prompt. For applications involving narrow automation, this process is inherently inefficient. A typical support ticket classification task requires a robust system prompt containing taxonomy definitions, task instructions, and few-shot examples. While these instructions may span several hundred tokens, the actual variable data—the ticket itself—often accounts for less than 15% of the total token count.
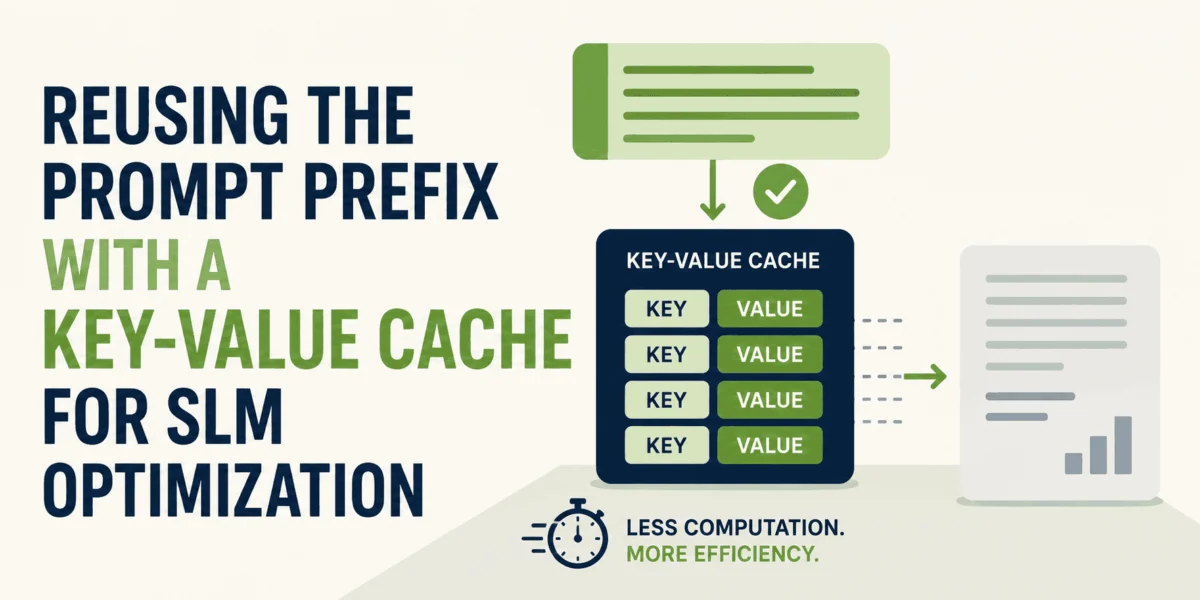
Under the naive "re-encode-everything" approach, the model calculates key and value vectors for the entire prompt, including the static instruction block, for every single transaction. Because the instruction block remains constant, the transformer is essentially performing the same mathematical operations on identical data millions of times per day. By isolating the static prefix and utilizing a Key-Value (KV) cache, developers can compute the hidden states for the instruction block once and reuse them for every subsequent request, effectively reducing the per-item pre-fill phase to only the unique tokens that change.
Benchmarking the Performance Gap
To quantify the impact of prefix caching, technical benchmarks were conducted using the Qwen2.5-0.5B-Instruct model. The testing environment consisted of an M2 MacBook Air equipped with 24GB of unified memory and a 16-core Neural Engine, utilizing the Hugging Face Transformers library.
In the baseline scenario, where the full prompt was re-encoded for every one of 600 sample tickets, the system required approximately 184.85 seconds to complete the batch. This resulted in an average latency of 308.1 milliseconds per ticket. By implementing a DynamicCache object to store the KV states of the static instruction prefix, the same workload was completed in 80.07 seconds. This represents a 57% reduction in total compute time, bringing the average latency per ticket down to 133.5 milliseconds.
These results illustrate a clear inverse relationship between the length of the static prompt and the efficiency gains achieved. As instruction blocks grow in complexity—often necessary for ensuring high-quality, reliable output in enterprise settings—the "cost" of re-encoding becomes progressively higher, making prefix caching an essential strategy for scaling SLM deployments.
Chronology of Optimization Strategies
The evolution of SLM efficiency can be traced through three primary phases of development. In the early stages, the focus was entirely on model size—shrinking parameters from hundreds of billions to sub-billion counts to fit on consumer hardware. The second phase, which includes the current exploration of prefix caching, involves optimizing the "data path."
- Model Quantization and Distillation: Initial efforts focused on compressing large models through techniques like float16 conversion or 4-bit quantization, allowing the 0.5B parameter models to run on edge devices.
- Output Space Constraint: As demonstrated in previous research, limiting the model’s vocabulary or output tokens—for instance, by only considering the logits of specific classification labels—drastically reduces the number of tokens the model needs to generate, effectively turning generative models into efficient discriminators.
- KV Cache Management: The current implementation of prefix caching represents the maturation of the inference pipeline. By moving beyond naive re-encoding, developers can treat the instruction set as a persistent "memory" layer, leaving the model to only process the "contextual delta" of each new request.
Technical Implementation Considerations
The transition to a cached-prefix workflow requires a rigorous approach to tokenization. Because the KV cache depends on precise token sequences, the split between the static prefix and the dynamic suffix must be "token-clean." If the encoding of the prefix and suffix separately does not match the encoding of the combined prompt, the cache will not align with the model’s internal state, leading to degraded performance or incorrect outputs.
Engineers must ensure that the chat template is handled manually or that the tokenizer settings remain perfectly consistent across all calls. Furthermore, during the inference loop, the attention mask must be adjusted to account for the position of the cached tokens. The model must be instructed that new tokens start at a position index equivalent to the length of the cached prefix, rather than at index zero. Once these constraints are satisfied, the output of the cached model is mathematically equivalent to the uncached version, ensuring that performance gains do not come at the cost of accuracy.
Broader Implications for Enterprise AI
The success of prefix caching in small-scale benchmarks has significant implications for enterprise AI infrastructure. Many organizations currently struggle with the "cold start" latency of LLMs, where the time-to-first-token is dominated by the processing of lengthy system prompts. In high-throughput environments, such as real-time customer support routing, financial document classification, or automated email triaging, a 50% reduction in latency can determine whether an automated system is viable or a failure.
Furthermore, this optimization strategy changes the economics of hosting. By reducing the compute load per request, organizations can increase the volume of tasks handled by a single GPU instance. For edge deployments—such as on-device AI in mobile applications or local server clusters—this efficiency allows for the use of smaller, more cost-effective hardware, effectively democratizing access to high-performance AI capabilities.
Future Perspectives
As SLMs continue to be refined, the industry is moving toward a standard where "narrow automation" is treated as a specialized engineering discipline. The era of treating every AI prompt as a novel, isolated query is rapidly closing. The future of the field lies in stateful inference, where the model maintains a persistent understanding of its operational context.
The technical community is expected to move toward even more granular caching strategies, including multi-tier caching where common "task types" are stored in a persistent cache, allowing the model to switch between different instruction sets instantly. While large language models (LLMs) often dominate the headlines, the practical, daily operations of the modern digital economy are likely to be powered by these optimized, smaller models. By mastering the intersection of model architecture and cache management, developers are building the foundational infrastructure that will support the next generation of automated, intelligent enterprise systems.
In conclusion, the reuse of prompt prefixes serves as a testament to the fact that optimization is often less about changing the model itself and more about how the system interacts with the model’s internal state. By treating instructions as static assets and keeping them in memory, developers can strip away the inefficiency of redundant compute, allowing small models to punch well above their weight class in production.