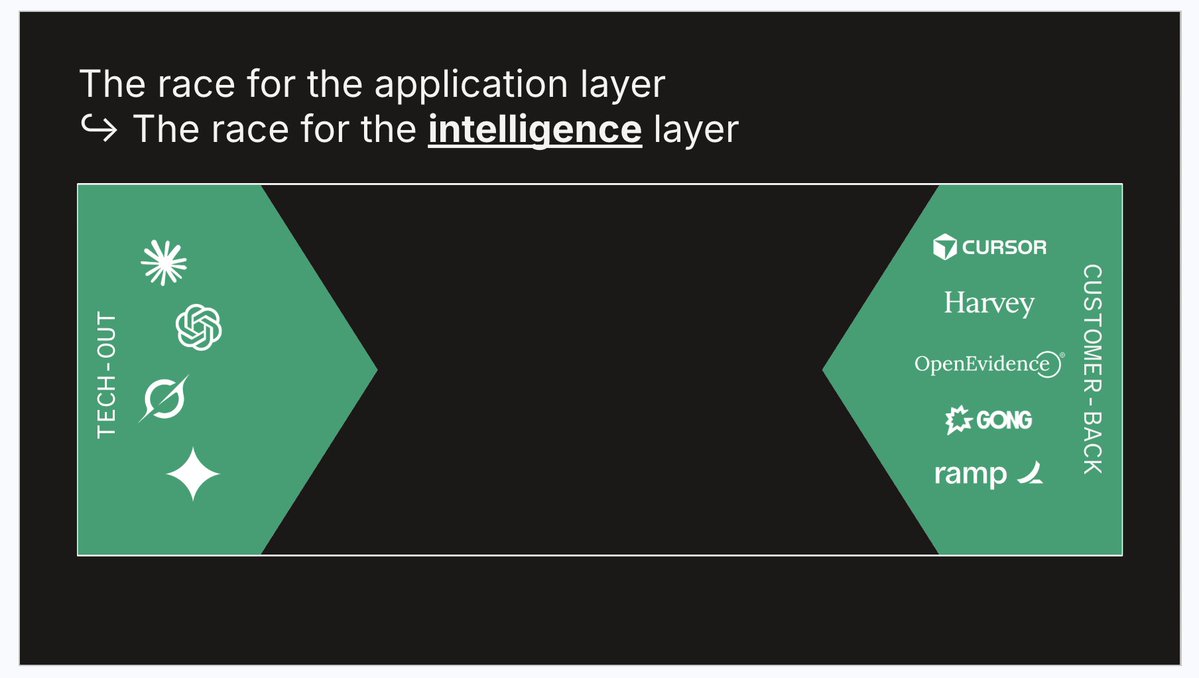
Published August 19, 2026, the artificial intelligence landscape is undergoing a profound structural shift. For the past several years, the race to deploy generative AI has centered on user interfaces, workflow optimization, and aggressive go-to-market strategies. However, industry leaders are increasingly recognizing that these elements represent only the surface of a much deeper contest. The ultimate battleground has shifted to the intelligence layer itself—the core foundational models, weights, and learning loops that dictate how software applications think, reason, and adapt.
This growing sentiment was crystallized recently when Palantir CEO Alex Karp publicly urged enterprises to "own the means of production." Shortly thereafter, Microsoft CEO Satya Nadella warned that relying exclusively on intelligence rented from external frontier labs carries a hidden, compounding toll: organizations pay twice, first through commercial API fees and second by surrendering the proprietary domain knowledge required to make those models useful.
These high-level warnings reflect an emerging operational reality across the technology sector. While renting intelligence from frontier model providers remains a viable strategy for general workloads, a growing cohort of pioneering companies is aggressively verticalizing its AI infrastructure. By moving beyond out-of-the-box APIs, these firms are building, shaping, and fine-tuning their own model weights to secure a competitive advantage.
The Catalyst: Convergence of Open-Weight Performance and Infrastructure Maturity
The impetus for this strategic pivot stems from two massive technological breakthroughs that have accelerated over the past year. First, the open-weight model ecosystem has closed the performance gap with proprietary frontier labs at an unprecedented pace. Releases such as Kimi K3 and GLM 5.2 have demonstrated that open models can achieve near-frontier baseline capabilities. Historically, fine-tuning open-weights was an exhausting treadmill; organizations would invest months customizing a model, only for a subsequent laboratory release to instantly render their gains obsolete. Today, starting from a high-performance open baseline allows developers to bypass that treadmill entirely.
Second, the independent post-training and infrastructure stack has matured dramatically. Companies specializing in data curation, synthetic data generation, and scalable inference—such as Mercor and Fireworks—have democratized access to the complex engineering machinery once exclusive to elite research labs. Equipped with robust evaluation frameworks, advanced harness engineering, and online learning capabilities, organizations can now deploy open models that outperform generalized frontier models within specific, high-stakes domains. Consequently, utilizing open weights has evolved from a compromise made for cost-savings into an existential strategic decision.

Strategic Drivers: Cost, Speed, Data Sovereignty, and Control
The decision to transition from renting to owning AI intelligence is dictated by a strict set of economic and operational imperatives. Organizations typically initiate this shift when reliance on external frontier APIs introduces constraints in four key areas:
- Escalating COGS: As an AI-driven product scales, inference costs tied to third-party APIs increase linearly with user engagement. For successful applications, owning and hosting a distilled, optimized model is often the only viable mechanism to protect gross margins.
- Latency and Speed: In high-velocity domains such as real-time code autocompletion and cybersecurity threat detection, milliseconds matter. Smaller, domain-specific custom models frequently outperform massive generalized models simply because they can process requests with significantly lower latency.
- Data Privacy and Proprietary Feedback: Relying on external APIs often requires transmitting sensitive enterprise data, customer interactions, and evaluation metrics across corporate perimeters. Companies operating in regulated sectors prefer to keep their learning loops strictly internal.
- Strategic Convergence: The historic boundary separating application developers from intelligence providers is rapidly dissolving. Frontier labs are increasingly building downstream applications, while application companies are moving upstream into training loops. To control their product destinies, software vendors must control the underlying learning loops.
The Technical Playbook: Evals, Harnesses, Post-Training, and Online Learning
To operationalize the ownership of intelligence, organizations are adopting a rigorous, four-step technical framework popularized by industry builders and platform architects.
1. Rigorous Evaluation (Evals)
As Gabe Pereyra of legal AI firm Harvey famously noted, "If you don’t have a good benchmark, you can’t train models." An effective evaluation framework consists of a standardized set of tasks featuring specific prompts, contextual data, and automated graders. While evaluations often begin as subjective "vibe-checks" by founders, successful companies formalize these assessments into repeatable metrics. For instance, Harvey constructed its proprietary Legal Agent Benchmark by translating complex legal work into over 1,200 distinct agent tasks spanning 24 practice areas, evaluated against more than 75,000 expert rubric criteria. Establishing a robust evaluation framework allows organizations to make objective, data-driven decisions regarding model selection rather than relying on guesswork.
2. Harness and Context Engineering
An autonomous AI agent typically comprises three components: the underlying model, the context, and the harness. According to LangChain founder Harrison Chase, the primary function of a harness is to deliver the correct context to the model at the exact moment it is needed. A well-engineered harness manages product logic, tool routing, memory allocation, retrieval-augmented generation (RAG), and fallback mechanisms. Furthermore, it ensures system inspectability, allowing engineers to trace every tool call, analyze context inputs, and diagnose failure points when a model encounters out-of-distribution tasks.
3. Targeted Post-Training
Once evaluations and harnesses are established, organizations can apply targeted post-training methodologies depending on their specific performance bottlenecks. As infrastructure expert Lin Qiao explains, missing factual knowledge requires simple RAG implementations rather than model retraining. However, incorrect output formats or behavioral drift can be corrected through supervised fine-tuning. For nuanced adjustments in product tone and style, preference tuning is deployed, while reinforcement learning (RL) is reserved for mastering specialized, complex workflows. When models prove overly resource-intensive, distillation techniques reduce latency and cost while preserving domain-specific efficacy.
4. Continuous Online Learning
The final frontier in owning AI infrastructure is establishing a production-level learning loop. As engineer Arjun Karanam has observed, while frontier models possess immense generalized intelligence, deploying them into a specialized enterprise environment is akin to introducing a brilliant academic researcher to an accounting firm on day one; what the model lacks is operational experience. By capturing "trajectories"—the complete audit trail of context viewed, tools invoked, outputs generated, and subsequent human edits—platforms like LangChain’s LangSmith enable continuous improvement. Failed tasks are systematically converted into new evaluation benchmarks, missing information is channeled into context memory, and erroneous tool responses trigger harness updates.

Broader Implications and Industry Outlook
The transition toward enterprise intelligence ownership introduces a fundamental trade-off. Relying exclusively on the closed-model stack—calling a frontier API, utilizing an out-of-the-box development harness, and applying basic prompting—offers a high operational floor with minimal friction, but ultimately caps long-term differentiation.
Conversely, embracing the open-source and custom-trained stack requires a significant commitment of specialized talent. Building small, de novo research teams—such as Harvey’s agile research unit, which achieved significant breakthroughs with a team of just seven people—demands a cultural shift toward rigorous publishing, open benchmarking, and active participation in the broader technical ecosystem.
Ultimately, this movement does not signal an abandonment of major AI research laboratories. The foundational giants will continue developing massive, generalized frontier models, which will remain essential for broad workloads. However, in parallel, forward-thinking product companies are cultivating their own specialized, domain-obsessed intelligence layers tailored precisely to their operational needs. In doing so, the broader technology ecosystem transitions from centralized dependence toward a diverse, highly resilient marketplace of specialized intelligence.